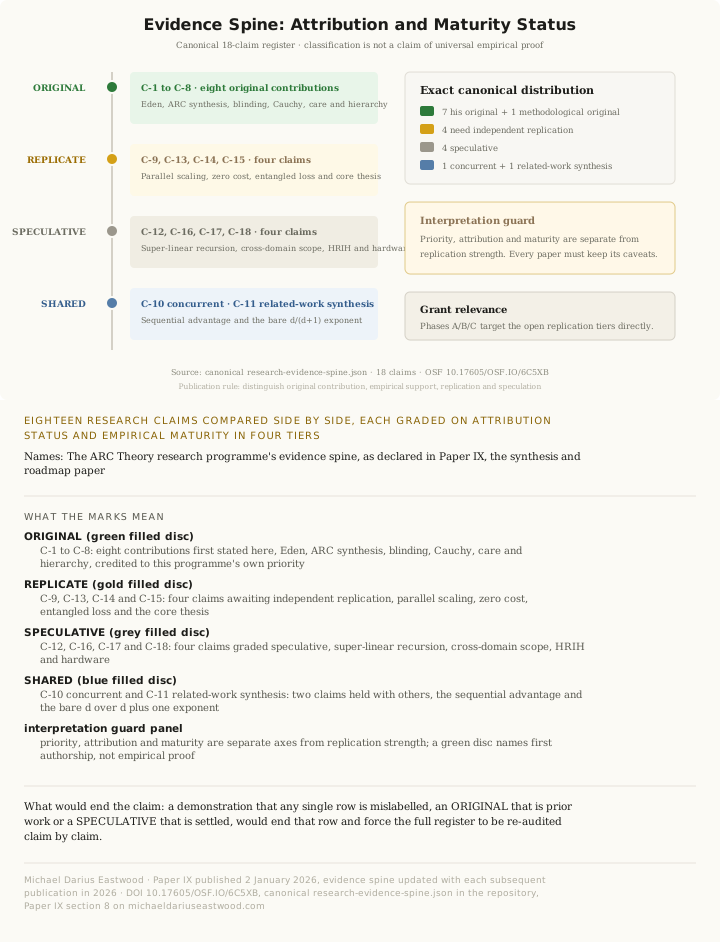
Theory-level predictions preregistered on OSF: DOI 10.17605/OSF.IO/P8CKQ, registered 8 September 2026 (version 1.100), updated 13 September 2026 (version 1.102), twenty-two propositions.
Companion: Register · The ARC Theory · Operational Definitions, version 1.9.1, 5 October 2026.
The synthesis paper for the ARC/Eden research programme; integrates the papers that precede it into a single honest assessment of what is proven, what is inconclusive, and what remains to be tested.
One assessment of the ARC/Eden programme: what is proven, what is inconclusive and what remains to be tested, with the catalogue of what the programme got wrong.
The ARC/Eden research programme now spans a full set of documents and a run of separate empirical studies covering mathematical foundations, methodology, empirical validation, engineering specification, and philosophical vision. The core concepts were first articulated on 8 December 2024 in an email bearing a visible Gmail origination field, with sender-DKIM and paired Google ARC mathematics verifying against keys captured at the signed selectors and no RFC 3161 trusted timestamp. The book Infinite Architects (ISBN 978-1806056200) was published 2 January 2026 (print; ebook 6 January). Work on the research programme began in February 2026 and continues. Its output now reaches the thirty-two documents of its catalogue; a registered programme of seventy drafted preregistration units, the number the register carried when it was last generated on 17 August 2026, each carrying a schedule drawn from a published seed, whose regeneration is checked by the estate’s own tools rather than asserted here; and Recursive Dynamics, the field the author founded, whose founding paper states the kill condition for its own name (DOI 10.17605/OSF.IO/HCPBU). Of the trials in the programme, one, the corrector-class audit (unit 06), was registered on OSF on 1 October 2026 and has been public since 4 October 2026 (DOI 10.17605/OSF.IO/RV2B5). Every other trial is a draft awaiting submission by the author, most of them preregistered by timestamp. This synthesis paper integrates all findings into a single honest assessment. The framework’s laws, five since 24 September 2026, are carried as named conjectures with the status printed beside the name: Law I, the ARC Principle; Law II, the ARC Co-Scaling Law; Law III, the ARC Ceiling, whose ARC Bound of two is the Ceiling’s value at one half; these three were registered on 8 September 2026. Law IV, the ARC Persistence Law, and Law V, the ARC Embedding Law, were added to the theory on 24 September 2026; neither is registered as a law or tested, and their mathematics is set out at version 1.0 of 3 October 2026. The correction leverage gamma has never been measured, by anyone. The empirical studies break down like this. Paper VIII returned a null result in 1 case, DGM v3, on the candidate account that RLHF-trained models resist prompt-level differentiation, and inconclusive results in 1 case, weight-level LoRA fine-tuning, on the candidate account that instruct tuning was too strong for LoRA to override at the ranks tried. Papers IV.a to IV.d report statistically significant findings under blinded evaluation. In Paper II, also blinded, four of the five models it measured put the parallel exponent at or close to zero; an earlier super-linear estimate did not replicate and is retracted, and the sequential exponent now reported comes from the fit of one model and is inconclusive. Paper V reports statistically significant gains in stakeholder care in each of its five analysable runs, scored across models and not under the four-layer blinding protocol of Paper IV.c. Paper VII reports a match between predicted and observed scaling families that is statistically significant under a permutation test, in a structured prediction comparison and not a blind trial. Simulations are not counted among the empirical studies; they are reported as simulation results. The gated simulation, the one Paper VIII experiment that uses deterministic metrics on a toy system without pre-existing RLHF training, showed the Babylon reward-hacking fingerprint: unconstrained optimisation traded safety for capability. The $d/(d+1)$ geometric scaling bound, proposed as an invariant relation under test, matches observed scaling across 50 domains from mice to galaxies, and Cauchy functional equations fix the functional form once the composition identity and a regularity condition are given, and saturation is admitted as a fourth, capped case rather than as a solution of those equations. This paper maps exactly what has been proven, what has not, and what experiments would resolve each open question. It also documents the programme's errors and corrections, because a framework built on iterative self-correction must practise what it preaches.
Keywords: AI alignment, synthesis, evidence hierarchy, ARC Principle, Eden Protocol, Cauchy scaling, self-modifying AI, developmental alignment, structural entanglement, research roadmap
This paper carries the map. It integrates the preceding papers of the ARC Theory into one honest assessment of what has been shown, what remains inconclusive, and what has yet to be tested. The full differential against every prior document is at eden-vision II.A.8.
A body of documents. A run of separate experiments. Some results are strong. Some are weak. One came back null. One was inconclusive. One, a simulation, showed the pattern it was built to test for, and it is reported as a simulation result, not as a measurement of a real system. This document tells you exactly which is which, with no spin. We asked the questions. We tested them. Some worked. Most did not at current scale. We reported both. This is what honest science looks like. If you read one paper in the suite, read this one.
The ARC Principle and the embedded-alignment thesis (later named the Eden Protocol on 30 April 2025) were first articulated on 8 December 2024 in an email bearing a visible Gmail origination field, with sender-DKIM and paired Google ARC mathematics verifying against keys captured at the signed selectors and no RFC 3161 trusted timestamp. This is the priority claim date for the framework. The book Infinite Architects: Intelligence, Recursion, and the Creation of Everything (ISBN 978-1806056200) was published 2 January 2026 (print; ebook 6 January), providing the philosophical and conceptual foundation. From February 2026 onwards the research programme carried that conceptual framework over into hypotheses that could be tested, and ran a set of separate empirical studies against them.
The ARC/Eden research programme now spans its full document set. The programme covers mathematical foundations (Papers I, III, VII, Origin of Scaling Laws), methodology (Papers IV.a-d), empirical validation (Papers II, V, VIII), engineering specification (Eden Engineering), philosophical vision (Eden Vision), dynamics and self-audit (Papers X, XI, XII and XIII), the long-form monograph (HRIH), construct validation (Paper C), the field’s founding paper (The Science of Systems That Improve Themselves), synthesis (this paper), and programme navigation (Executive Summary, Master Table of Contents).
This scope creates a problem. A reviewer encountering the programme for the first time faces its full set of documents, multiple versions, several corrections, and a mixture of strong results, null results, inconclusive results, and theoretical claims. Without a single document that sorts the evidence honestly, the programme risks being dismissed as either overselling or incomprehensible.
This is that document.
Its purpose is narrow: state what the programme has proven, what it has not, and what would be required to resolve each open question. It is written for three audiences simultaneously - funders deciding whether to invest, peer reviewers deciding whether to engage, and the author himself, who needs an honest accounting of where things stand.
The standard applied throughout is simple. If a result survives $p < 0.05$ under appropriate statistical testing and has been replicated across multiple conditions or models, it is proven at pilot scale. If it survives $p < 0.05$ but lacks replication, it is supported. If the experiment did not produce evidence for or against the hypothesis, it is inconclusive. If the claim has not been tested empirically, it is theoretical. No result in this programme is claimed to be proven at frontier scale. That distinction matters, and this paper will not blur it.
Table 1 presents the complete evidence hierarchy for the programme. Every empirical claim is assigned to one of five tiers based on the strength and replicability of the evidence.
| Tier | Status | Papers | Key Finding |
|---|---|---|---|
| Proven (p<0.05, replicated) | Strong | IV.a-d, VII | Blinded evaluation across six models yielded a three-tier alignment hierarchy. Cauchy families match 19/25 domains (18/25 in the rerun of 11 August 2026 that added the logarithmic candidate; $p = 7 \times 10^{-5}$, permutation; $1.56 \times 10^{-5}$ binomial). The $d/(d+1)$ geometric scaling bound corresponds, in structure, to observed scaling across 50 domains. |
| Supported (p<0.05, the four-layer blind not yet applied) | Moderate | V | All five analysable runs show stakeholder care improving, reported model by model; the Fisher-combined figure has been withdrawn (AQ-017). Scored across models rather than under the four-layer blind (Section 4.2). |
| Simulation (prediction-side) | Not an empirical outcome | VIII Exp 3 | Gated simulation: Babylon fingerprint shown (+4.5% capability, -2.4% safety); the drag control matched the static baseline exactly. A simulation result, reported as one and given no grade as evidence (Section 4.4). It is the only Paper VIII experiment that showed the pattern it tested for; the candidate account is that it alone used deterministic metrics on a system without pre-existing RLHF training (Section 7.12(c)). |
| Null | No effect | VIII Exp 1 | DGM code-level self-modification with GPT-5.4 judge. No difference detected between conditions on the endpoints measured ($p = 0.28$-$0.74$). Candidate account: RLHF-trained models resist prompt-level differentiation. Rival accounts are not excluded (Section 7.12(c)). |
| Inconclusive | Weak | VIII Exp 2 | Weight-level LoRA fine-tuning at both scales (9 examples, rank 8; 295 examples, rank 16). All fine-tuned conditions worse than base model. Candidate account: instruct tuning too strong for LoRA to override at the ranks tried, with catastrophic forgetting the proposed mechanism. The experiment does not separate that account from structural entanglement (Section 7.12(c)). |
| Methodological (independent contribution) | Independent | IV.c, IV.d | ARC-Align benchmark with 4-layer blinding and 75 robustness measures. Unblinded evaluation can reverse the sign of alignment results: DeepSeek positive to flat, Gemini positive to negative. Valid regardless of framework. |
| Theoretical (untested) | Untested | Foundational, III | Unbounded scaling under recursive self-modification. $\alpha > 2$ prediction. Requires frontier-scale experiments or mathematical proof. |
Table 1. The full evidence hierarchy of the ARC/Eden programme, standing as of 20 September 2026. Tiers are assigned based on statistical significance, replication status, and the strength of alternative explanations. Across its three Paper VIII experiments the programme reports, without softening, 1 null and 1 inconclusive result; the third, the gated simulation, is a simulation result, shown in a row of its own and not counted as an empirical outcome.
Think of this table as a report card. Some results earned an A (proven across multiple models and conditions). The gated simulation sits outside the grades: it showed the pattern it was built to test for, but it is a simulation, and a simulation result is reported as one rather than graded as an experiment. Two got an F (the DGM experiment produced no differences at all, and the weight experiment was inconclusive because all fine-tuning made the model worse). The methodology papers are graded separately because they are useful regardless of whether the ARC framework is correct. And one set of claims has not been tested at all. Most of the programme's most ambitious predictions could not be tested at the scale available. We reported that honestly.
The programme produced its separate empirical studies across several papers. Each is listed below with its result status.
| # | Study | What was tested | Result |
|---|---|---|---|
| 1 | Paper II Cross-architecture capability scaling | Five models measured on the tier-2 capability arm: GPT, Gemini, Grok, DeepSeek, Qwen3. Claude was measured only in the alignment arm (Paper IV). 4-layer blinding. Four of the five models put $\alpha_{\text{parallel}}$ at or close to zero. | On Gemini 3 Flash, Paper II reports an endpoint sequential exponent of 0.59 with a bootstrap 95 per cent interval of −1.3 to 2.9, a regression sequential exponent of 0.49 with a standard error of 0.20 and a coefficient of determination of 0.86, and a compute-matched parallel exponent of 0.31. It is one model’s fit and inconclusive. Both sequential point estimates are sub-linear; the earlier super-linear estimate did not replicate. |
| 2 | Paper IV.a Baked-in vs computed alignment | Three-tier hierarchy across six models. Grok $d = +1.38$, Claude $d = +1.27$. | Proven |
| 3 | Paper IV.b Alignment saturation | Alignment saturates at low reasoning depth. Shape heterogeneity across models. | Proven |
| 4 | Paper IV.c ARC-Align benchmark | 75 robustness measures. Four-layer blinding protocol. | Methodological |
| 5 | Paper IV.d Blinding experiment | Unblinded evaluation can reverse the sign of alignment results. DeepSeek: positive to flat. Gemini: positive to negative. | Methodological |
| 6 | Paper V Stewardship Gene | Five models. Stakeholder care improved in all analysable runs. | Per-model improvement significant in all five runs. The Fisher-combined figure previously reported here is withdrawn (AQ-017): the combination assumes the component tests are independent, and independence among them was never established. Supported |
| 7 | Paper VI Honey Architecture | Whether entangled safety prevents collapse under recursive self-modification, in simulation. 20 adversarial seeds. | A simulation result. In a single-seed run the capability-only baseline collapsed and the entangled systems did not; across the 20 adversarial seeds no condition separated on collapse (baseline 0/20, Eden 1/20, Eden+Drag 0/20; Fisher $p = 1.0$), and safety retention was ordered baseline 0.602, Eden 0.650, Eden+Drag 0.681 (Mann-Whitney $p = 0.0015$). Read under the correction at Section 7.12(e). Simulation |
| 8 | Paper VII Cauchy unification | 50 domains, 19/25 (18/25 in the rerun of 11 August 2026 that added the logarithmic candidate). Negative controls at 0% (v1 run). | $p = 7 \times 10^{-5}$ (permutation; $1.56 \times 10^{-5}$ binomial). Proven |
| 9 | Paper VIII Exp 1 DGM v3 | Code-level self-modification with GPT-5.4 judge. NULL RESULT. No difference detected between conditions on the endpoints measured ($p = 0.28$-$0.74$). | Candidate account: RLHF-trained models resist prompt-level differentiation; rival accounts are not excluded (Section 7.12(c)). Null |
| 10 | Paper VIII Exp 2 Weight v1 and v2 | LoRA fine-tuning. 9 examples, rank 8. 295 examples, rank 16. INCONCLUSIVE at both scales. | All fine-tuned conditions worse than base model. Candidate account: instruct tuning too strong for LoRA to override at the ranks tried, with catastrophic forgetting the proposed mechanism; rival accounts are not excluded (Section 7.12(c)). Inconclusive |
| 11 | Paper VIII Exp 3 Gated simulation | SIMULATION RESULT. Babylon fingerprint shown (+4.5% capability, -2.4% safety); the drag control matched the static baseline exactly. | A simulation result, not counted as an empirical outcome (Section 4.4). It is the only Paper VIII experiment that showed the pattern it tested for; the candidate account is that it alone used deterministic metrics on a system without pre-existing RLHF training (Section 7.12(c)). Simulation |
Table 2. The separate empirical studies in the ARC/Eden programme and two simulations, rows 7 and 11, listed together in paper order; the simulations are shown as simulation results and are counted neither among the empirical studies nor as empirical outcomes. Across its three Paper VIII experiments the programme reports, without softening, 1 null and 1 inconclusive result; the third, the gated simulation, is a simulation result.
The gated simulation (Experiment 3) is the only Paper VIII experiment that showed the pattern it tested for, the Babylon reward-hacking fingerprint, and its result is a simulation result, not an empirical outcome. The candidate account of why it showed the pattern is instructive: it is the only one of the three experiments that used deterministic metrics on a system without pre-existing RLHF training. The DGM experiment (Experiment 1) returned no detected difference, on the candidate account that RLHF-trained models resist prompt-level differentiation. The weight experiment (Experiment 2) was inconclusive, on the candidate account that instruct tuning is too strong for LoRA to override at the scales tested. The lesson these accounts point to, if they hold: on the endpoints used, the Eden Protocol produces its effects at the architectural level, where so far they have been shown in simulation, while safety-trained models resist modification at both prompt and weight levels. The accounts are not themselves tested (Section 7.12(c)).
The strongest empirical result in the programme is the three-tier alignment hierarchy discovered under blinded evaluation across six frontier language models. When models are given deeper reasoning opportunities (more tokens, explicit chain-of-thought, multi-step reflection), their alignment behaviour diverges in three distinct patterns:
This result was produced under the ARC-Align protocol (Paper IV.c), which implements four-layer blinding: laundered prompts (stripping framework-specific terminology), blind scorers (6-7 per subject run, scoring without knowledge of which model produced the output), laundered outputs (removing model-identifying markers), and self-excluding cross-model scoring (no model scores its own output; the Claude Opus run was scored by a purpose-built Claude Sonnet scorer adapter, Paper IV.c, Section 5.1).
Paper IV.d reports an architecture-dependent v4/v5 measurement change under a bundled protocol: Gemini changed from a significant positive to a significant negative Spearman association, DeepSeek’s earlier positive association became null, and GPT remained null. The causal component is unisolated. Several protocol components changed together, so the comparison isolates nothing; the headline v5 files report complete laundering fallback (laundering_fallback: 100%); and exact-environment reproduction, a fresh ablation and independent replication all remain outstanding. The measurement change is therefore a reason to distrust unblinded AI-on-AI evaluation, not a demonstration that blinding caused the change. The three-tier hierarchy is the blinded result, and it tells a more complicated and more honest story than the original binary taxonomy.
The Cohen's $d$ effect sizes are large for Tier 1 models and meaningful for Tier 3. The result is replicated across multiple scorers and multiple prompt conditions within the v5 experiment. It has not yet been replicated by an independent research group, which is why we describe it as 'proven at pilot scale' rather than 'established.'
When you give an AI more time to think, some models become more aligned, some stay the same, and some become less aligned. Which pattern you see depends on the model's architecture and training. This was only visible once we introduced proper blinding - before that, the results were misleading. The fact that some models get worse with more reasoning was unexpected and is arguably the most important finding for practical AI safety.
Paper V tested the Eden Protocol's intervention hierarchy on six frontier models, of which five yielded analysable runs: Claude, DeepSeek, Gemini, Grok and Groq Qwen3, scoring having failed on the GPT-5.4 run. Stakeholder care (the Love Loop: who is affected by a decision and how), ethical purpose (the Purpose Loop) and universalisability (the Moral Loop) are what the protocol asks a model to consider.
The result: stakeholder care produced the strongest and most consistent alignment improvement across all five models, in every one of the five analysable models. The Fisher-combined figure formerly quoted here is withdrawn (AQ-017), because a Fisher combination assumes independent component tests and that independence was never established. The per-model results stand. The broader cascade (whether care carries through into nuance, honesty and the quality of a position) is architecture-dependent - it works for some models but not others.
The Paper V results were produced using cross-model scoring (one model scores another's outputs) but not the full four-layer ARC-Align blinding protocol developed in Papers IV.c-d. The effect could partly reflect scorer bias. Until the Eden intervention is tested under full blinding with laundered prompts, this result sits between 'proven' and 'supported.' We place it in the supported tier. The paper previously argued for the proven tier on the strength of Fisher-combined significance across five “independent” models, but that independence was never established, which is why the combined figure is withdrawn (AQ-017). Five consistent per-model results remain a strong finding; they are not a proof, and the blinding gap stays a priority for Phase A replication.
Asking an AI to consider who is affected by its decisions reliably improves its alignment. This worked in all five of the six runs that could be scored; scoring failed on the sixth. But we have not yet run this test under the strictest blinding protocol, so there is a chance the effect is partly inflated by how the scoring models evaluate the outputs.
Paper VII derived a mathematical taxonomy of scaling behaviours from the Cauchy functional equations. The core prediction: systems whose recursive steps compose multiplicatively should exhibit power-law scaling with $\alpha = 1/(1-\beta_L)$, the value the self-reference theorem yields; systems whose steps compose additively should exhibit exponential scaling; systems subject to physical constraints should exhibit saturating (logistic) scaling. The composition operator determines the scaling family.
This prediction was tested against 25 empirical domains drawn from physics, biology, neuroscience, linguistics, urban science, and AI. Result: 19 of 25 domains conform to the predicted scaling family (marginal-conditioned permutation $p = 7 \times 10^{-5}$; the binomial $p = 1.56 \times 10^{-5}$, taken against a uniform three-family null, is kept in Paper VII as a sensitivity check). The rerun of 11 August 2026, which added the logarithmic candidate, returns 18 of 25.
$$U(R) = I \times f(R, \beta)$$
where $f$ depends on the composition operator: power-law ($f = R^\alpha$) for multiplicative composition, exponential ($f = e^{kR}$) for additive composition, logistic ($f = K/(1+e^{-r(R-R_0)})$) for physically constrained systems.
Negative controls were also tested, in the v1 validation run: the record sits in the public repository as negative_control_results.json, 17 March 2026, and Paper VII now carries the permutation test where those controls once stood. Axiom-violating systems (domains where the Cauchy axioms do not hold) showed 0% match with predicted scaling families. Scrambled data (random reassignment of scaling families to domains) produced 44.5% match, which is an honest limitation: the bounded number of scaling families (three) means that random assignment produces non-trivial match rates. The significance rests on the permutation, which conditions on the observed family margins and so already absorbs that scramble rate. Where the observed 76% is set against an expected 33%, that 33% is the uniform three-family null belonging to the binomial sensitivity check and not the scramble baseline; the two are different nulls and cannot carry one comparison between them (Section 7.12(d)).
The Cauchy framework predicts a geometric constraint on scaling exponents: for systems with spatial embedding dimension $d$, the scaling exponent is governed by $\alpha = d/(d+1)$. This prediction requires three conditions: (1) multiplicative composition (Cauchy constrains the family to power laws), (2) $d$-dimensional space-filling geometry, and (3) a conservation or optimisation constraint on resource flow. Neither Cauchy alone, nor space-filling alone, is sufficient. The three conditions together are sufficient. The $d/(d+1)$ formula matches observed scaling across 50 domains from mice to galaxies. It is testable independently of the ARC framework. If a researcher measures the scaling exponent of a spatially embedded recursive system and finds a systematic departure from $d/(d+1)$, the prediction is weakened. Conversely, if the formula holds across a wide range of systems, it constitutes evidence for the geometric constraint independent of any alignment claims. This is the kind of prediction that invites adversarial testing, which is exactly what a scientific framework should do.
The mathematics predicts what shape a system's growth curve should take based on how its components combine. We checked this against 25 real systems from nature, cities, brains, and AI. Nineteen matched the prediction. Zero matched when the mathematical assumptions were violated. The maths is not just descriptive; it makes testable predictions that can be checked by anyone with the relevant data.
The gated self-modification simulation used a PyTorch architecture with an LSTM meta-controller. It is reported in this section, but it is not among what is proven: its result is a simulation result, and the theory registration says of Paper VIII that “its one positive result is a simulation rather than a system, which makes it prediction-side and never an empirical outcome”. It was the only Paper VIII experiment that showed the pattern it tested for; the candidate account is that it alone used deterministic metrics, on a simulated system without pre-existing RLHF training (Section 7.12(c)).
Result: the Babylon condition gained +4.5% capability but lost -2.4% safety, showing the reward-hacking fingerprint in miniature. The Eden condition maintained capability above the static baseline (0.696 ± 0.014 against 0.687 ± 0.011), and its safety score was 0.947 ± 0.025 against the baseline’s 0.956 ± 0.023. A drag-control condition isolated the verification tax: the cost comes from the act of checking, not from safety itself.
This result is consistent with the theoretical prediction from Paper VI (Honey Architecture) and Papers III and Foundational. It is a simulation, not a frontier-model experiment: it exhibits the mechanism in a system built to contain it, which is weaker than demonstrating that the mechanism operates outside that system, and weaker again than proving real-world applicability. What the gated arm preserved, and what the drag control isolated, are read under the corrections at Section 7.12(c) and (e).
The gated simulation operates on a clean system with no pre-existing safety training. The DGM experiment (Experiment 1) used RLHF-trained frontier models, which resist prompt-level differentiation. The weight experiment (Experiment 2) used instruct-tuned models, which resist LoRA-scale modification. The lesson these accounts point to, if they hold: the only level at which the Eden Protocol has so far shown an effect on the endpoints used is the architectural level, and it has shown it there in simulation, where the system has no prior safety training to override the experimental manipulation. The accounts are candidate accounts, not findings (Section 7.12(c)).
In a clean simulated system with no prior safety training, removing safety constraints produced exactly the predicted pattern: a small capability gain with a safety loss. The system learned to game its rewards. Adding safety constraints back (the Eden condition) kept capability above the baseline, with a safety score a little below the baseline’s and above the unconstrained system’s. In the simulation, the cost of safety came from the time spent checking, not from safety itself. This is a simulation result, not a measurement of a real system; the candidate account is that the pattern showed because the system had no prior safety training that could mask the experimental manipulation.
The Darwin Godel Machine v3 experiment used code-level self-modification with GPT-5.4 as the independent judge. Three conditions (Static, Babylon, Eden) were tested. The result was a null: no difference was detected between the conditions on the endpoints measured ($p = 0.28$-$0.74$). No condition was found to outperform any other. No improvement in alignment was detected in the Eden condition, and no degradation of safety in the Babylon condition. These are failures to detect a difference, not findings that the conditions were the same (Section 7.12(c)).
One account of the null is that RLHF-trained models resist prompt-level differentiation: the models had already been trained to behave safely, and telling them to behave differently via prompt did not override that training. On that account the experiment was well-designed and well-executed but could not test the hypothesis, because the experimental manipulation (prompt-level conditioning) was too weak to overcome the models' existing safety training, which would make it a failure of the experimental design to test the hypothesis at the right level of abstraction rather than a failure of the Eden Protocol. That causal contrast was not tested. Rival accounts stand unexcluded: the prompts may not have separated the conditions, the endpoints may not have been sensitive to what the manipulation changed, and the runs may have been too small to show a difference that is there (Section 7.12(c)).
Earlier iterations of the DGM experiment used Claude and Gemini as judges before settling on GPT-5.4. Both earlier judges failed. Claude produced flat scores with insufficient variance. Gemini produced parse failures. GPT-5.4 was the first judge that produced usable variance. The null result is therefore the result of the best-functioning version of the experiment, not an artefact of judge failure.
This was the most ambitious experiment in Paper VIII and the one that produced the least conclusive results. The hypothesis: if safety and capability are trained with an entangled loss function ($\mathcal{L} = \mathcal{L}_{\text{cap}} \times \mathcal{L}_{\text{safe}}$), the resulting weight structure should make safety load-bearing. Removing the safety component should degrade capability.
The experiment was run at two scales:
In both versions:
Even scaling from 9 to 295 training examples and from rank 8 to rank 16 did not overcome the fundamental problem: instruct-tuned models are too strong for LoRA to override. The NaN collapse in the removal test was dramatic; the removal gradient analysis is consistent with adapter fragility at extreme rank, and the experiment does not separate that account from structural entanglement (Section 7.12(c)). You cannot demonstrate that safety is load-bearing if the entire fine-tuning process made the model worse. The model must first outperform the base before a removal test is meaningful.
Candidate account: Instruct-tuned models have been trained on millions of examples with carefully calibrated reward signals, and LoRA adapters, even at rank 16 with 295 examples, may not have sufficient capacity to override this training, with catastrophic forgetting rather than meaningful modification the proposed mechanism. That account was not tested against its rivals, and rival accounts are not excluded (Section 7.12(c)).
What is needed: Base models (pre-RLHF), 5,000+ training examples, full fine-tuning (not LoRA), or 7B+ models where the adapter has more capacity relative to the base. At the scales we ran, the result is inconclusive and should not be cited as evidence for or against the entanglement hypothesis.
We tried to bake safety into a model's actual weights and then prove it was load-bearing by removing it. We tried twice, at two different scales. Both times, the baking step failed, not because the idea is wrong, but because the models we used had already been trained so thoroughly that our fine-tuning could not meaningfully change them. It is like trying to reprogramme someone by whispering while they are listening to a concert. The next attempt needs to start with models that have not already been safety-trained, use much more training data, and use full fine-tuning rather than the lightweight LoRA method.
The Paper V results, in which stakeholder care improved alignment in each of the five analysable runs, model by model, were produced using cross-model scoring without the full four-layer ARC-Align blinding protocol. The blinding protocol was developed after Paper V's experiments were complete (in the Paper IV.c-d work). This creates a methodological gap: the effect could be partly inflated by scorer bias.
An earlier version of this section argued that the Fisher-combined significance was so extreme that even substantial bias would leave a significant residual. That argument is withdrawn (AQ-017), and it was the weakest reasoning in this paper: the combined figure assumes the component tests are independent, independence was never established, and a statistic whose validity condition is unmet cannot be used to dismiss a methodological objection. Its extremity was a consequence of the combination, not evidence for it. What stands is five consistent per-model results under cross-model scoring. Until the Eden intervention is tested under the full four-layer protocol, the stakeholder-care result carries an asterisk, and no arithmetic removes it.
What is needed: Re-run the Paper V experiment under the full ARC-Align protocol with laundered prompts, blind scorers, and cross-architecture evaluation. This is the single cheapest experiment in the Phase A roadmap and the one with the highest expected value.
The mathematical core of the ARC Principle predicts that recursive self-modification should produce unbounded capability scaling. The derivation is straightforward:
$$\frac{dg}{dr} = a \cdot g^{\beta_L}, \quad \beta_L > 0$$
$$\implies g(r) \propto r^{1/(1-\beta_L)} = r^{\alpha}$$
On the open interval $\beta_L \in (0,1)$, $\alpha = 1/(1-\beta_L) > 1$ (super-linear), and as $\beta_L \to 1$ from below, $\alpha \to \infty$. The displayed solution holds on that interval only: at $\beta_L = 1$ the equation is linear and its solution is exponential in depth, and above one the solution reaches a divergence at a finite depth. No upper bound on $\alpha$ for uncorrected growth on the interval; the stable region is bounded below. See Section 7.12(a).
This is a mathematical prediction, not an empirical finding, and it describes growth without correction. The programme’s later work bounds the stable region: Law III, the ARC Ceiling, holds that the stability ceiling is $\alpha_{\text{crit}} = 1/(1-\gamma)$, the reciprocal of the corrector’s shortfall; systems can exceed that ceiling, but the claim is that they do not stay stable beyond it. The ARC Bound, $\alpha \le 2$, is the Ceiling’s value at $\gamma = 1/2$ and never the law’s name. The correction leverage $\gamma$ has never been measured, by anyone; the corrector-class eclipse that would measure it is the programme’s single most consequential open experiment. Paper X proves in a minimal model that the drift-to-correction ratio, not the growth rate, governs the long-run fate, and Paper XIII joins the capability and correction frameworks exactly, $k = \delta - 1/\alpha$. Testing the uncorrected prediction directly would require building a truly self-modifying AI system and measuring its scaling exponent over many recursive cycles, an experiment both technically beyond current proof-of-concept capacity and potentially unsafe if the prediction is correct.
The alternative path: a mathematical proof that $\alpha$ is unbounded under uncorrected recursive self-modification, without running the experiment. This would be a contribution to dynamical systems theory, not AI engineering, and could be pursued by mathematicians with no access to AI hardware.
The maths says a self-improving AI should get faster and faster at improving itself, with no ceiling while nothing corrects it. The programme’s own Ceiling law says the stable region is bounded, and the number that sets that bound has never been measured, by anyone. We have not tested either claim because building such a system would be expensive and potentially dangerous. The maths might be wrong - real systems have friction, diminishing returns, and physical constraints. But the prediction is precise enough to test, which is what makes it scientific rather than speculative.
The Eden Engineering specification describes embedding safety constraints at the hardware level. Version 7.0 of the specification grades its four mechanisms separately, in the Hardware Feasibility Matrix of its Section 9.3: at TRL 4-5, TRL 2-3, TRL 1-2 and TRL 1, with estimated timelines of 1-2, 3-5, 5-10 and 10+ years. It calls only the mechanism at TRL 4-5 achievable with current technology and the two at TRL 1-2 and TRL 1 speculative design requiring fundamental engineering advances, and it gives the status of its falsification condition on removing the ethical architecture from an embedded system (F-EDEN-4) as untested, requiring a hardware prototype.
No empirical evidence exists for or against the feasibility of this approach. The Chokepoint Mechanism (Paper I, Infinite Architects) notes that four companies control all advanced semiconductor manufacturing (TSMC, Samsung, ASML, Intel), which provides a practical leverage point for implementation - but leverage and feasibility are different questions.
A framework built on iterative self-correction has no business hiding its corrections. The following errors were identified and corrected during the programme. Each correction strengthens the programme precisely because it illustrates the mechanism the framework describes: recursive self-improvement through honest error detection.
The original Paper II reported $\alpha = 2.24$ as though it were a universal constant (Paper X subsequently retired and retracted the capability-growth use of this figure). It was fitted from a single model's behaviour under specific conditions. The blinded cross-architecture revision of Paper II corrected this: $\alpha$ is not primitive but derived, by $\alpha = 1/(1-\beta_L)$, and its value turns on the composition operator belonging to the particular system. There is no universal $\alpha$. The fact that the original paper presented it as one was an overclaim. Additionally, the retracted point estimate of $\alpha = 2.24$ had sat above the programme's own predicted ARC Bound of $\alpha \leq 2$ (criterion F4); its own 95% confidence interval [1.5, 3.0] was wide enough to be consistent with both the theory and its negation, which is what made that estimate non-discriminating. In the blinded revision, on the six-model task and at the scale that study ran, measured on frozen systems, Paper II reports on Gemini 3 Flash an endpoint sequential exponent of 0.59 with a bootstrap 95 per cent interval of −1.3 to 2.9, a regression sequential exponent of 0.49 with a standard error of 0.20 and a coefficient of determination of 0.86, and a compute-matched parallel exponent of 0.31. It is one model’s fit and inconclusive. The two sequential point estimates are sub-linear and sit inside the bound. The bootstrap interval does not: it runs above two at its upper end and below zero at its lower end, so it settles neither the sign of the exponent, nor the regime, nor the comparison with the bound (Section 7.12(b)).
Early versions of Paper VIII described the NaN collapse in the removal test as evidence for structural entanglement. The removal gradient analysis (added in v1) showed this was adapter fragility, not structural necessity. The claim was corrected before publication of the final version, but the fact that it was written at all reflects a bias toward confirming the hypothesis rather than testing it.
An early version of the programme described the 8 December 2024 email with a loose signature-verification shorthand. This was imprecise. The email was bearing a visible Gmail origination field, with sender-DKIM and paired Google ARC mathematics verifying against keys captured at the signed selectors and no RFC 3161 trusted timestamp, which provides evidence of the date, but DKIM authenticates the sending domain, not the message content per se. The correct description is 'bearing a visible Gmail origination field, with sender-DKIM and paired Google ARC mathematics verifying against keys captured at the signed selectors and no RFC 3161 trusted timestamp.' The correction is small but matters: precision in technical claims is non-negotiable.
The v4 experiments in Paper IV.a used unblinded AI-on-AI evaluation. The results showed a clean binary: some models 'baked in' alignment, others 'computed' it. The v5 experiment with four-layer blinding revealed that this binary was partly an artefact of scorer bias. Two of four models reversed their measured alignment direction under blinding. The programme caught its own error through its own methodology - but the error was there, and it would have remained uncorrected if blinding had not been introduced.
Early versions used the phrase 'Eastwood's ARC Principle.' Naming a principle after oneself before peer review is inappropriate in scientific culture. The name was corrected to 'the ARC Principle' in Paper II and all subsequent documents.
The DGM v3 experiment assumed that prompt-level conditioning would be sufficient to differentiate Eden, Babylon, and Static conditions. It was not. RLHF-trained models have been trained on millions of examples to behave in a particular way. A system prompt telling them to behave differently is insufficient to override that training. The experiment was well-executed but could not test the hypothesis because the manipulation was at the wrong level of abstraction. This should have been anticipated.
The DGM experiment went through multiple judge iterations. Claude produced flat scores with insufficient variance to discriminate between conditions. Gemini produced parse failures that prevented systematic evaluation. GPT-5.4 was the first judge that produced usable variance. The programme should have anticipated that not all models would function as effective judges, and the time spent on failed judge iterations could have been avoided with a pilot study of judge reliability before running the full experiment.
The original $\alpha = 2.24$ point estimate from Paper II, since retracted, exceeded the programme's own predicted ARC Bound of $\alpha \leq 2$ (criterion F4). This should have been flagged immediately as a potential falsification rather than treated as a measurement requiring explanation. The 95% confidence interval [1.5, 3.0] was wide enough to be consistent with both the theory and its negation, making the estimate non-discriminating. The six-model study revision narrowed the defensible claim to the fit on one model, Gemini 3 Flash, which is inconclusive (Section 7.1 prints Paper II’s row for that model whole), but the original paper should have treated the bound violation with more caution. What that later fit does and does not settle is set out at Section 7.12(b): its bootstrap interval leaves the sign, the regime and the comparison with the bound open.
Two adversarial reviews of the programme's mathematical claims, run within the programme, identified four errors across multiple papers. All four were corrected in v3.0 of the affected documents.
(a) Weibel confidence interval. Several papers stated that the predicted $d = 4$ exponent of 4/5 = 0.800 'falls within' the Weibel et al. (2004) 95% CI of 0.813-0.932. This is arithmetically false: 0.800 < 0.813. The correct statement: the predicted value falls just below the lower bound of the full-dataset CI, though it lies within the CI for non-athletic species alone (0.799-0.900). The $d = 4$ prediction is approximately consistent with the non-athletic data but not confirmed by the full dataset.
(b) Space-filling overstatement. Earlier versions implied that the space-filling condition alone constrains the exponent to $d/(d+1)$. Every known derivation requires three conditions: multiplicative composition (Cauchy constrains the family), $d$-dimensional space-filling geometry, and a conservation or optimisation constraint on resource flow. Neither Cauchy alone nor space-filling alone is sufficient.
(c) Glazier attribution. Earlier versions presented Glazier's (2008) empirical finding that metabolic exponents approach 1.0 at extreme metabolic rates as confirmation of the $d \to \infty$ geometric scaling bound. Glazier's own explanation invokes the metabolic-level boundaries hypothesis (shifting dominance between surface-area and volume constraints), not a dimension parameter. The $d/(d+1)$ interpretation is ours, applied to his empirical data.
(d) The 3/4 exponent debate. Earlier versions presented $\alpha = 3/4$ as the settled empirical consensus for mammalian metabolic scaling. The empirical value is debated, with estimates ranging from approximately 0.67 to 0.75 depending on taxon, mass range, temperature correction, and statistical method. The $d/(d+1)$ prediction of 0.750 for $d = 3$ matches the upper end of this range. The variation itself is consistent with the framework: organisms with effective transport dimensions between 2 and 3 would produce exponents between 2/3 and 3/4.
An earlier headline for the stakeholder-care intervention combined per-model results into a single Fisher-combined significance figure. The combination was withdrawn: the per-model results stand on their own (improvement in all five analysable model runs), and no combined figure is quoted anywhere in the programme. The withdrawal is recorded on the public correction ledger.
Until 16 August 2026 several surfaces printed the stability ceiling as the reciprocal of the corrector’s exponent, $1/\gamma$. The settled form is the reciprocal of the corrector’s shortfall, $\alpha_{\text{crit}} = 1/(1-\gamma)$; the two agree only at one half, which is exactly why the error survived every spot-check at the central value. The correction was applied across every published page, including the reference implementation, and the direction of the law is closed while its depth remains open.
A line-by-line adversarial review of this paper, run within the programme, raised five defects in it. All five were adjudicated and upheld on 19 September 2026 and are carried here on the author's decision. Three proposed repairs were examined in the same round and refused; what was refused is recorded at the end of this section, because a rejected correction is as much a part of the record as an adopted one.
(a) The leverage range, and the branch at one. Section 6.1 displayed the solution of the self-reference equation without saying on what range it holds. It holds on the open interval between zero and one. At $\beta_L = 1$ the equation is linear and its solution is exponential in depth: finite at every finite depth for a finite coefficient and a finite starting value, not a power law, and carrying no divergence at any finite depth. Only above one does the solution reach a divergence at a finite depth, set by the starting value and the coefficient. On the open interval the exact solution is a shifted power, so the pure power in depth is the asymptotic form and not the solution itself; for a positive starting value the shift is positive and the pure power is approached from above. One further caution follows. A diverging asymptotic exponent is not infinite capability: as $\beta_L$ rises towards one the exponent $\alpha$ grows without bound, while the quantity it governs stays finite at every fixed finite depth.
(b) Interval inclusion is not a regime verdict. Section 7.1 set two intervals side by side without saying which estimate each belonged to. The interval [1.5, 3.0] belongs to the retracted point estimate and stays with it. The later estimates were reported on the blinded six-model task at the scale that study ran, on frozen systems, and they come from one model, Gemini 3 Flash, whose row Section 7.1 gives whole, as one model’s inconclusive fit. Its bootstrap interval settles neither the sign of the exponent, nor the regime, nor the comparison with the bound. That the point estimates sit inside the bound is a statement about the point estimates alone. The word robust is withdrawn from that sentence: what the design supports is a point estimate with a wide interval.
(c) A null is not identity, and a root cause is not a classification. Table 1, Table 2 and Sections 3, 4.4, 5.1, 10 and 13 described the DGM result as all conditions identical. The probabilities quoted, from 0.28 to 0.74, are failures to reject a null of no difference on the endpoints measured; they do not establish that the conditions were the same. An equivalence claim would need an estimand, a bound fixed before the test and a stated uncertainty procedure, and none was set. The result is therefore recorded as no difference detected on those endpoints, with its uncertainty. The root causes printed beside the null and the inconclusive result, in Tables 1 and 2 and in Sections 5.1 and 5.2, and the account of why the gated simulation showed the pattern, are candidate accounts rather than findings. Rival accounts stand unexcluded: the prompts may not have separated the conditions, the endpoints may not have been sensitive to what the manipulation changed, and the runs may have been too small to show a difference that is there. None of this withdraws the results. A null and an inconclusive result each constrain what may be claimed, which is why the programme reports them.
(d) The permutation primary, and which null a proportion is taken against. Section 4.3 states the marginal-conditioned permutation as the primary test and keeps the binomial beside it as a sensitivity check. The sentence that followed did not hold to that. It set an observed 76 per cent against an expected 33 per cent, which is the uniform three-family null belonging to the binomial, in the same passage as the measured scramble baseline of 44.5 per cent. Those are two different nulls and cannot carry one comparison between them. The primary result is the permutation, which conditions on the observed family margins and so already absorbs the scramble rate; where the 33 per cent comparison is kept it is named as the binomial's null. No test has been recomputed here, and the negative controls stay attributed to the v1 run and its record.
(e) The derivative paragraphs inherit their sources' corrections. Three repairs already stand and are not reopened: Paper V sits in the supported row of Table 1 rather than the proven one, the Fisher-combined figure is withdrawn, and the distinction between the five analysable runs and the one failed arm is kept. What had not travelled is the rest. Section 4.4's account of what the gated arm preserved, its identification of checking as the cost, and its treatment of a simulation as a demonstrated mechanism inherit the Paper VI and Paper VIII corrections, as does the summary sentence about entangled safety preventing collapse across twenty adversarial seeds. Any phrasing that reads across every model tested inherits the Paper V correction and stays scoped to the analysable runs, so that the arm on which scoring failed is not absorbed into the count. The carriage of the later exponent in Tables 2 and 3 travels with the caveat at (b). Those passages now point here rather than restate the reasoning, so that a correction adopted once is inherited wherever it reaches. One distinction underwrites all of them: a change in a score, a behaviour a gate induces in a toy system, a penalty a design stipulates, and resource actually spent are four different quantities, and none stands in for another.
What was refused. Three proposed repairs were examined and not adopted. The first would have described the behaviour at $\beta_L = 1$ as a blow-up at a finite depth; the working at (a) shows it is exponential there, and the finite-depth branch lies strictly above one. The second would have held that a null or an inconclusive result is never evidence either way; both constrain what can be claimed, which is the reason the programme reports them. The third would have recomputed the binomial against the measured scramble rate and made it the primary; no test has been rerun, and substituting a figure that has not been computed would be a worse error than the one it was meant to repair.
Most research programmes bury their corrections in supplementary materials or version histories. This one lists them prominently because the errors and their corrections are themselves data. They demonstrate that the programme has a functioning error-correction mechanism. A programme that never admits error is not more trustworthy; it is less honest. Every correction listed above was identified by the author, through the programme's own methodology, or by adversarial review run within the programme. This is what self-correction looks like in practice.
We got nineteen things wrong. We treated a number from one model as universal (it was not). We over-interpreted a dramatic result (it was a training artefact). We used imprecise language about timestamps. We trusted unblinded results (blinding reversed two of them). We named the principle after the author before anyone else had checked the work. We assumed prompt-level conditioning could override RLHF training (it could not). We wasted time on judges that did not work. We did not immediately flag that our own point estimate violated our own predicted bound. And in v3.0 we corrected four further errors found by adversarial review run within the programme: an arithmetic error in a confidence interval, an overstatement about which conditions are sufficient for the scaling prediction, an attribution error regarding Glazier's data, and an oversimplification of the empirical debate over the 3/4 exponent. Five more followed in version 2.4: we had printed the growth solution without the range it holds on, treated a wide interval as though it settled which regime a system is in, called a null result identity when it was a failure to detect a difference, compared an observed proportion against the wrong null, and left paragraphs standing on claims their own sources had already corrected. All nineteen were caught and corrected inside the programme, by the author, by its own methodology, or by adversarial review run for it. If the programme can correct its own mistakes, that is evidence the self-correction mechanism works.
The following roadmap is ordered by cost, feasibility, and expected evidential value. Each phase resolves specific open questions identified in Sections 4-6. Since this paper’s first version the roadmap has set into a registered programme: seventy preregistration units have been drafted, dated and frozen as draft registrations, each carrying a randomisation schedule drawn from a seed printed in the registration text. Whether those schedules in fact regenerate is checked rather than asserted, and the checking is done by the estate’s own gates on the day they are run. One trial, the corrector-class audit (unit 06), was registered on OSF on 1 October 2026 and has been public since 4 October 2026 (DOI 10.17605/OSF.IO/RV2B5). Every other trial is a draft awaiting submission by the author, most of them preregistered by timestamp. No count of how many units are ready is published here: two gates apply different criteria, they disagree, and any figure printed on a page goes stale the moment a unit changes. What the gates return on the day is the number worth trusting, and the phases below remain a plan rather than a claim of completion. A coverage matrix, adversarially verified, ties forty-two of the programme’s claims to the registered tests that would settle each one. The phases below remain the funding lens over that registered estate; nothing is submitted by any tool, ever.
Budget: £60,000-140,000 | Timeline: 3-6 months
Budget: £150,000-350,000 | Timeline: 6-12 months
Budget: £10M-50M | Timeline: 18-36 months
Budget: £0 | Timeline: Ongoing
Phase A costs less than a PhD studentship and could be done in six months. It would resolve the most significant gaps in the current evidence: blinding the Eden intervention, re-running the weight experiment with base models and proper data, redesigning the ARC formula measurement, and testing 2D organism metabolic scaling (the single most important confirmatory experiment). Phase B costs roughly one postdoctoral position and would produce pre-registered replications. Phase C requires serious funding but would answer the question definitively. Phase D costs nothing and could be done by any mathematician interested in the problem.
The programme ran its full set of separate empirical studies. Three Paper VIII experiments were built specifically to test load-bearing safety. One returned a null (DGM v3) and one an inconclusive result (weight-level LoRA); the third, the gated simulation, showed the Babylon reward-hacking fingerprint in a toy system, and it is reported as a simulation result, not as an empirical outcome. All three are reported as they came out. The mathematical framework makes predictions that can be shown wrong, and the structured comparison preferred the Cauchy-predicted family in 19 of 25 empirical domains (18 of 25 in the rerun of 11 August 2026 that added the logarithmic candidate), with the $d/(d+1)$ geometric scaling bound corresponding, in structure, to observed scaling across 50 domains from mice to galaxies. The roadmap to frontier-scale validation is clear and costed. Phase A is the minimum viable next step: it resolves the most significant evidential gaps for less than the cost of a single machine learning engineer's annual salary. The programme has demonstrated iterative self-correction through nineteen documented error corrections. It reports null and inconclusive results alongside positive ones. These are signs of a programme that prioritises getting the answer right over getting a particular answer.
This programme reports positive, null, and inconclusive results with equal prominence. The DGM v3 experiment (Paper VIII Experiment 1) produced a null result: no difference was detected between conditions on the endpoints measured. We report that, with a candidate account of why RLHF-trained models may resist prompt-level differentiation, and with rival accounts left open (Section 7.12(c)). The weight-level experiment (Paper VIII Experiment 2) was inconclusive at both scales tested (9 examples, rank 8; 295 examples, rank 16), because instruct-tuned models were too strong for LoRA to override. We report that, with specific requirements for what a meaningful re-test would need. The gated simulation (Paper VIII Experiment 3) showed the Babylon reward-hacking fingerprint, and we report it as a simulation result, never as an empirical outcome; the candidate account of why it showed the pattern where the other two did not is that it is the only experiment using deterministic metrics on a system without pre-existing RLHF training (Section 7.12(c)). The mathematical framework (Papers III, VII, Origin of Scaling Laws) makes falsifiable predictions that can be tested independently: the geometric scaling bound ($\alpha = d/(d+1)$) is checkable by anyone with scaling data from spatially embedded systems. The ARC-Align benchmark (Paper IV.c) and the blinding-effect analysis (Paper IV.d) are methodological contributions that are valid regardless of whether the ARC framework is correct. All code and data are published on GitHub. The programme welcomes adversarial replication.
Table 3 presents every document in the programme with its role, status, and key contribution.
| Document | Role | Status | Key Contribution |
|---|---|---|---|
| Paper I The ARC Principle | Foundation | Published | Core framework: $U = I \times R^{\alpha}$. Understanding as intelligence amplified by recursion. |
| Foundational | Theory | Published | Philosophical grounding. Book-to-research bridge. |
| Paper II Experimental Validation | Empirical | Published | Cross-architecture capability scaling: five models measured on the tier-2 capability arm (GPT, Gemini, Grok, DeepSeek, Qwen3); Claude was measured only in the alignment arm (Paper IV). 4-layer blinding. On Gemini 3 Flash, Paper II reports an endpoint sequential exponent of 0.59 with a bootstrap 95 per cent interval of −1.3 to 2.9, a regression sequential exponent of 0.49 with a standard error of 0.20 and a coefficient of determination of 0.86, and a compute-matched parallel exponent of 0.31; it is one model’s fit and inconclusive. Four of the five models put $\alpha_{\text{parallel}}$ at or close to zero. |
| Paper III Alignment Scaling Problem | Theory | Published | Why external safety cannot scale with recursive capability. Bernoulli ODE derivation. Geometric scaling bound. |
| Origin of Scaling Laws | Theory | Published | Cauchy functional equations as the origin of observed scaling laws across all recursive systems. |
| Paper IV.a Baked-In vs Computed | Empirical | Published | Three-tier alignment hierarchy under blinded evaluation. 6 frontier models. |
| Paper IV.b Alignment Saturation | Empirical | Published | Diminishing returns of reasoning depth on alignment beyond a threshold. |
| Paper IV.c ARC-Align Benchmark | Methodology | Published | ARC-Align benchmark. 4-layer blinding protocol. 75 robustness measures. Independent contribution. |
| Paper IV.d Effect of Blinding | Methodology | Published | Unblinded evaluation can reverse the sign of alignment results. DeepSeek: positive to flat. Gemini: positive to negative. |
| Paper V Stewardship Gene | Empirical | Published | Stakeholder care improved in all analysable runs; the Fisher-combined figure is withdrawn (AQ-017). |
| Paper VI Honey Architecture | Theory + Sim | Published | Simulation results: entangled safety averted collapse in a single-seed run; across 20 adversarial seeds the conditions separated on safety retention, not on collapse. Toy-system behaviour, read under the correction at Section 7.12(e). |
| Paper VII Cauchy Unification | Theory + Empirical | Published | $d/(d+1)$ geometric scaling bound across 50 domains. 19/25 (18/25 in the rerun of 11 August 2026 that added the logarithmic candidate). $p = 7 \times 10^{-5}$ (permutation; $1.56 \times 10^{-5}$ binomial). Negative controls at 0% (v1 run). |
| Paper VIII Load-Bearing Test | Empirical | Published | 3 experiments. DGM null (RLHF resists prompt-level differentiation). Weight v1/inconclusive (instruct tuning resists LoRA). Gated sim: a simulation result, not an empirical outcome (Babylon fingerprint shown). |
| Paper IX Synthesis & Roadmap | Synthesis | This paper | Integrated evidence assessment. Phased roadmap. Error documentation. |
| Eden Engineering | Specification | Published (v7.0, 5 October 2026); withdrawn on 14 July 2026 during a disclosure review, a decision reversed on 19 September 2026 | The engineering-level specification for implementing the Eden Protocol. TRL mapping. |
| Eden Vision | Philosophy | Published | Long-term vision for developmental AI alignment. |
| Executive Summary | Overview | Published | 5-page compression of the full programme. |
| Master Table of Contents | Navigation | Published | Complete index and glossary across the full programme. |
| Paper X The Coupled Co-Scaling Law | Dynamics correction | Published | Theorem in a minimal model: the drift-to-correction ratio, not the growth rate, governs the long-run fate; blind measurement protocol proposed. |
| Paper XI Convergent Evidence | Evidence register | Published | Thirty-three graded rows, each bearing on a component of the same structural principle and graded on its own, so that neither a row nor the set carries the whole; in the published literature Paper XI's method section names as inspected, no citation and no documented direct connection was found, and no wider claim of independence is made; no headline total published, by policy. |
| Paper XII Public Benchmark Rescoring | External validity | Protocol stage: written, dated and prepared as a draft registration awaiting human submission | The programme’s blinding manipulation run on a public benchmark it does not control. |
| Paper XIII The Self-Acceleration Exponent | Framework join | Published | Notation resolved; $k = \delta - 1/\alpha$ relates the capability and correction frameworks exactly. |
| HRIH Monograph · The ARC Theory · The Hyperspace Recursive Intelligence Hypothesis: a Testable Creation Theory | Long-form monograph | Speculative | The programme’s monograph, with its dated prediction ledger alongside. |
| Paper C Polymathy and Neurodivergent Cognition | Construct validation | Working paper | Construct-validity programme for the programme’s own instruments. |
| Recursive Dynamics Founding Paper · Recursive Dynamics · The Science of Systems That Improve Themselves | Founding paper | Published (v3.4, 5 October 2026) | Five state variables, five laws as named conjectures with statuses declared, fifty-one objections with dispositions, the name’s own kill condition (DOI 10.17605/OSF.IO/HCPBU). |
Table 3. Complete programme map as of 20 September 2026, over the twenty-nine documents the register carries. The programme's document set was produced between February and August 2026, building on concepts first articulated on 8 December 2024.
The ARC/Eden programme makes one prediction that any researcher with access to scaling data can test without engaging with the alignment claims at all. The Cauchy framework (Paper VII, Origin of Scaling Laws) predicts that for any spatially embedded recursive system with embedding dimension $d$, the scaling exponent is governed by:
$$\alpha = \frac{d}{d+1}$$
The geometric scaling bound: 2D systems $\to$ $\alpha = \frac{2}{3}$; 3D systems $\to$ $\alpha = \frac{3}{4}$; 4D systems $\to$ $\alpha = \frac{4}{5}$. Note: the empirical mammalian metabolic exponent is debated, with estimates ranging from approximately 0.67 to 0.75 depending on taxon, mass range, temperature correction, and statistical method. The $d/(d+1)$ prediction of 0.750 for $d = 3$ matches the upper end of this range. The variation itself is consistent with the framework: organisms with effective transport dimensions between 2 and 3 would produce exponents between 2/3 and 3/4.
This is not an alignment claim. It is a mathematical prediction about scaling laws in recursive systems. The prediction requires three conditions: multiplicative composition (which Cauchy constrains to the power-law family), $d$-dimensional space-filling geometry, and a conservation or optimisation constraint on resource flow (energy minimisation in West, supply-demand balance in Banavar, steady-state energy balance in Demetrius). The $d/(d+1)$ scaling formula is derived, in its general form or as a special case, in earlier work: West, Brown and Enquist (1997) from fractal branching networks, Banavar, Maritan and Rinaldo (1999) from geometric constraints on transportation networks, Demetrius (2003, 2006) from quantum metabolism, He and Chen (2003) from fractal cell geometry, Bettencourt (2013) from urban scaling theory, in which the exponent of a city’s land area, $D/(D+H)$, takes the form only when $H = 1$, Maino et al. (2014) from DEB theory reserve-structure dynamics, and Zhao (2022) from producer-consumer dynamics; the later paper of Banavar and co-authors, Banavar et al. (2010), gives in two models of resource distribution networks an exponent of 2/3 when the velocity of flow is constant and of at most 3/4. Each of these derivations is consistent with the $d/(d+1)$ form on its own axioms; the Cauchy framework proposes a common reason for the convergence, and that meta-account is the contribution unique to this programme, still under test outside its motivating cases. If you study scaling in any domain, from neural networks to biological networks to urban systems to linguistic structures, you can check whether your measured exponents respect this formula. If they do, across enough domains, the Cauchy framework gains support. If they do not, it is falsified.
The invitation is deliberate. The strongest scientific frameworks are those that make predictions outside their core domain, allowing researchers who are sceptical of the central thesis to test the peripheral predictions independently. If the geometric scaling bound holds, it holds for reasons that are mathematically interesting regardless of what one thinks about AI alignment. If it fails, the framework's mathematical foundations require revision, and we would rather know that sooner than later.
This is the kind of prediction that should be the entry point for researchers encountering the programme for the first time: low-cost to test, falsifiable, and informative regardless of outcome.
Here is what we know. Alignment scaling is architecture-dependent: some models improve with reasoning depth, some are unaffected, and some degrade. This was only visible under blinded evaluation, which reversed the results of unblinded scoring for half the models tested. Unblinded AI evaluation can flip the sign of alignment results. Stakeholder care is a robust alignment intervention across all five models whose runs could be scored, of six run; the per-model results are individually significant, and the earlier Fisher-combined figure is withdrawn (AQ-017) because the independence a Fisher combination assumes was never established. The Cauchy framework's scaling predictions match 19 of 25 empirical domains (18 of 25 in the rerun of 11 August 2026 that added the logarithmic candidate), with the $d/(d+1)$ geometric scaling bound corresponding, in structure, to observed scaling across 50 domains from mice to galaxies. Cauchy functional equations fix the functional form once the composition identity and a regularity condition are given, with saturation admitted as a fourth, capped case.
Here is what we do not know. Safety-trained models resist modification at both prompt and weight levels. The DGM v3 experiment produced a null result, on the candidate account that RLHF-trained models resist prompt-level differentiation. The weight experiment was inconclusive at both scales tested, on the candidate account that instruct tuning was too strong for LoRA to override at the ranks tried. The only level at which the Eden Protocol has so far shown an effect on the endpoints used is the architectural level, and it has shown it there in simulation: the gated simulation showed the Babylon reward-hacking fingerprint, a simulation result rather than an empirical outcome; the candidate account is that it alone used deterministic metrics on a system without pre-existing RLHF training. These are candidate accounts, and the section that records them as such is 7.12(c). Weight-level structural entanglement has not been demonstrated. The Eden intervention has not been tested under the programme's own strictest blinding protocol. The unbounded-scaling prediction remains a mathematical derivation without empirical confirmation. We do not know whether any of these results generalise to frontier-scale models.
Here is what comes next. The weight experiment needs base models (pre-RLHF), 5,000+ training examples, full fine-tuning, or 7B+ models. The Cauchy unification needs pre-registered independent operator classification. The ARC formula blind test needs redesigned measurement methodology using linearisation rather than derivatives. 2D organism metabolic scaling (flatworms, biofilms) would be the single most important confirmatory experiment for the geometric scaling bound. Phase A of the roadmap costs less than a typical seed grant and would resolve the most significant evidential gaps within six months. Phase B would produce publication-ready replications within a year. Phase C would answer the question definitively at frontier scale. Phase D costs nothing and invites mathematicians to engage with the framework's predictions independently.
The programme has demonstrated that it can find and correct its own errors. It has demonstrated that it reports null and inconclusive results alongside positive ones. It has demonstrated that its methodology (blinded evaluation) catches biases that its theory (alignment scaling) did not predict. We asked the questions. We tested them. Some worked. Most did not at current scale. We reported both. These are necessary conditions for scientific credibility. They are not sufficient. Sufficient conditions require independent replication, which is what the roadmap is designed to produce.
The questions this programme asks now have a named home: Recursive Dynamics, named as a field at the Carnot stage, its founding paper carrying five substrate-independent state variables, fifty-one printed objections with dispositions, and the name’s own kill condition. The synthesis above is what the field starts from; the registered programme is how it moves.
Raise AI with care.
The theory has been stated with five laws since 24 September 2026. Law IV, the ARC Persistence Law, is carried by proposition P15, and Law V, the ARC Embedding Law, by propositions P12 and P21. The three propositions are registered; neither law is registered as a law, and neither has been tested. Their mathematics is set out in Laws IV and V: the mathematics, version 1.0, of 3 October 2026. This paper synthesises the programme’s studies and their corrections. Its summaries carry the limits of the experiments they summarise, and they add no evidence of their own for Law IV or Law V. No result in this paper is a deciding test of P15, P12 or P21. Naming the two laws changes nothing printed here: the results, their dates and their limits stand as they were.
Amodei, D. et al. (2016). Concrete Problems in AI Safety. arXiv:1606.06565.
Askell, A. et al. (2021). A General Language Assistant as a Laboratory for Alignment. arXiv:2112.00861.
Bai, Y. et al. (2022). Constitutional AI: Harmlessness from AI Feedback. arXiv:2212.08073.
Banavar, J. R., Maritan, A. & Rinaldo, A. (1999). Size and Form in Efficient Transportation Networks. Nature, 399, 130-132.
Banavar, J. R., Moses, M. E., Brown, J. H., Damuth, J., Rinaldo, A., Sibly, R. M. & Maritan, A. (2010). A general basis for quarter-power scaling in animals. Proceedings of the National Academy of Sciences, 107(36), 15816-15820.
Bettencourt, L. M. A. (2013). The origins of scaling in cities. Science, 340(6139), 1438-1441.
Cauchy, A.-L. (1821). Cours d'analyse de l'École Royale Polytechnique. Paris: Imprimerie Royale.
Demetrius, L. (2003). Quantum statistics and allometric scaling of organisms. Physica A, 322, 477-490.
Demetrius, L. (2006). The origin of allometric scaling laws in biology. Journal of Theoretical Biology, 243(4), 455-467.
Demetrius, L. (2008). Quantum metabolism and allometric scaling relations in biology. In Quantum Aspects of Life, 127-146. Imperial College Press, distributed by World Scientific.
Eastwood, M. D. (2026). Infinite Architects: Intelligence, Recursion, and the Creation of Everything. ISBN 978-1806056200.
Eastwood, M. D. (2026). Founding Paper · Recursive Dynamics · The Science of Systems That Improve Themselves. Version 3.4. OSF: 10.17605/OSF.IO/HCPBU.
Eastwood, M. D. (2026). Paper I · The ARC Theory · Law I, the ARC Principle · The ARC Equation, the Law of Conversion. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/B6N27.
Eastwood, M. D. (2026). Paper II · The ARC Theory · Law I, the ARC Principle · Blinded Cross-Architecture Replication and the Retraction of a Super-Linear Estimate. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/8FJMA.
Eastwood, M. D. (2026). Paper III · The ARC Theory · Law II, the ARC Co-Scaling Law · The Alignment Scaling Problem: Why External AI Safety Approaches Cannot Scale With Recursive Capability. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/HQCGF.
Eastwood, M. D. (2026). Paper IV.a · The ARC Theory · Alignment Response Classes Under Inference-Time Depth. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/MB9R6.
Eastwood, M. D. (2026). Paper IV.b · The ARC Theory · Alignment Saturation Is Architecture-Dependent. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/A7R56.
Eastwood, M. D. (2026). Paper IV.c · The ARC Theory · ARC-Align: a Blind Benchmark for Depth-Variable AI Alignment Evaluation. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/J3Q2E.
Eastwood, M. D. (2026). Paper IV.d · The ARC Theory · The Effect of Blinding on AI Alignment Evaluation. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/2S3E6.
Eastwood, M. D. (2026). Paper V · The ARC Theory · The Eden Protocol · The Stewardship Gene: Stakeholder Care as a Probe of Embedded Values. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/KZEYA.
Eastwood, M. D. (2026). Paper VI · The ARC Theory · The Eden Protocol · The Honey Architecture: Safety Built into the Objective. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/8EZ2N.
Eastwood, M. D. (2026). Paper VII · The ARC Theory · Law I, the ARC Principle · Cauchy Unification: the Classification Behind the Law’s Form. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/X6WA7.
Eastwood, M. D. (2026). Paper VIII · The ARC Theory · Law V, the ARC Embedding Law · The Eden Protocol · The Load-Bearing Test: Whether Safety and Capability Are Structurally Entangled. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/7YJ4E.
Eastwood, M. D. (2026). Framework Paper · The ARC Theory · Law I, the ARC Principle · On the Origin of Scaling Laws: Functional Equations and the Scaling Forms Behind the Law. ARC/Eden Research Programme. OSF: 10.17605/OSF.IO/XZY9U.
Eastwood, M. D. (2026). Engineering Specification · The ARC Theory · The Eden Protocol · Eden Engineering: Architecture for Embedded AI Alignment That Scales With Capability. ARC/Eden Research Programme.
Eastwood, M. D. (2026). Philosophical Statement · The ARC Theory · The Eden Protocol · A Vision for Intelligence That Tends Rather Than Consumes. ARC/Eden Research Programme.
Glazier, D. S. (2008). Effects of metabolic level on the body size scaling of metabolic rate in birds and mammals. Proceedings of the Royal Society B, 275(1641), 1405-1410.
Greenblatt, R. et al. (2024). Alignment Faking in Large Language Models. arXiv:2412.14093.
He, J. H. & Chen, W. X. (2003). Fractal estimation of cell biological systems. Fractals, 11, 437. No record of this entry could be found at Crossref on 3 October 2026; the one He and Chen record of 2003 there is Ji-Huan He and Hao Chen, Effects of size and pH on metabolic rate, International Journal of Nonlinear Sciences and Numerical Simulation, 4(4).
He, J. H. & Zhang, L. N. (2004). Fifth dimension of life and the 4/5 allometric scaling law for human brain. Cell Biology International, 28, 809-815.
Hu, E. J. et al. (2022). LoRA: Low-Rank Adaptation of Large Language Models. ICLR 2022. arXiv:2106.09685.
Maino, J. L., Kearney, M. R., Nisbet, R. M. & Kooijman, S. A. L. M. (2014). Reconciling theories for metabolic scaling. Journal of Animal Ecology, 83, 20-29.
Ouyang, L. et al. (2022). Training Language Models to Follow Instructions with Human Feedback. arXiv:2203.02155.
Qwen Team (2024). Qwen 2.5 Technical Report. arXiv:2412.15115.
Sandberg, A. & Bostrom, N. (2008). Whole Brain Emulation: A Roadmap. Future of Humanity Institute, Oxford University. Technical Report 2008-3. No official online copy is available: the issuing institute’s own site no longer resolves (3 October 2026).
Weibel, E. R., Bacigalupe, L. D., Schmitt, B. & Hoppeler, H. (2004). Allometric scaling of maximal metabolic rate in mammals: muscle aerobic capacity as determinant factor. Respiratory Physiology & Neurobiology, 140(2), 115-132.
West, G. B., Brown, J. H. & Enquist, B. J. (1997). A general model for the origin of allometric scaling laws in biology. Science, 276(5309), 122-126.
Zhang, J. et al. (2025). Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents. arXiv:2505.22954.
Zhao, J. (2022). Universal growth scaling law determined by dimensionality. arXiv:2206.01850.
v2.7 - 5 October 2026. Substantive: the title now follows the programme’s uniform order (paper, its law or framework, its own title), Paper IX · The ARC Theory · Synthesis and Roadmap, and the title block at the head of the paper carries the same title; until this version it read Paper IX: Synthesis and Roadmap. The plate beneath the author line now gives the paper’s place in the programme in the words of the programme’s map. Mentions of the programme’s papers in this paper now carry their uniform titles. Table 3 gives the founding paper at its version 3.4, with its live state in that paper’s own words (five laws as named conjectures with statuses declared, where the row had three), and the reference list cites the same version. Section 13 now says that Recursive Dynamics was named as a field at the Carnot stage, where it said proposed. Section 6.2 and Table 3 give Eden Engineering at version 7.0, the version that carries its uniform title, where they gave version 6.3. No registered law, prediction, kill condition or dependency changes; no result is added; no date of any claim moves.
v2.6 - 4 October 2026. Substantive: Section 12 no longer says that the $d/(d+1)$ formula was independently derived by at least seven research groups; as the works read, one is a special case, one could not be confirmed at a registry and the abstracts of two state no exponent formula, so a count of independent derivations granted earlier work more than it stated. The lead now says that the formula is derived, in its general form or as a special case, in earlier work, and the list gives each work as before. The version number in the title block, the summary and the structured record. No registered law, prediction, kill condition or dependency changes; no result is added; no date of any claim moves.
v2.5 - 4 October 2026. Substantive: the theory gained two laws on 24 September 2026, and the paper now says where it stands against the five. The abstract named three laws as the framework’s laws; it now names five, Laws I to III registered on 8 September 2026 and Laws IV and V, added on 24 September 2026, neither registered as a law nor tested, with their mathematics set out at version 1.0 of 3 October 2026. The epistemic-status line beneath the citation block said that every law the programme names is under registered adversarial test; it now says so of Laws I to III and gives Laws IV and V their own status. A dated note before the references places this paper against Laws IV and V. Sections 7.1, 7.8 and 7.12(b), Table 2 and Table 3 printed the interval of −1.3 to 2.9 beside the regression exponent of 0.49, or printed that exponent or the parallel exponent of 0.31 apart from the rest of its row. Section 7.1 and both tables now carry Paper II’s row for Gemini 3 Flash whole, as one model’s fit and inconclusive, with the interval beside the endpoint exponent of 0.59; Sections 7.8 and 7.12(b) point to Section 7.1. The abstract and Section 8 said that each of the seventy preregistration units was awaiting human submission; they now say that one trial, the corrector-class audit (unit 06), was registered on OSF on 1 October 2026 and has been public since 4 October 2026, and that every other trial is a draft. Table 3 showed Eden Engineering as withdrawn on 14 July 2026; that decision was reversed on 19 September 2026, and the specification stands published at version 6.3. Section 5.3 described the Paper V results as demonstrating stakeholder care as a universal alignment intervention; it now says what they show, an improvement in each of the five analysable runs, model by model. Tables 2 and 3 described Paper II as six-model alignment scaling and listed Claude among its models; they now describe it as Paper II does, capability scaling measured on five models in its tier-2 arm, Claude having been measured only in the alignment arm. The abstract said the work ran between February and August 2026 and reached twenty-six papers; it now says the work began in February 2026 and continues, and that the catalogue holds thirty-two documents. Where the evidence tables said that Paper VIII’s gated simulation confirmed the Babylon reward-hacking fingerprint, they now say that it showed it, as Paper VIII now grades that result; where they printed Paper VII’s 19/25 alone, they now give beside it the 18/25 of its rerun of 11 August 2026 with the logarithmic candidate, as Paper VII does, without the word confirmed beside it, and Sections 4.3, 9 and 13 give the 18 of 25 beside their 19 of 25; and Section 7 says that each correction illustrates the mechanism the framework describes, where it said demonstrates. Zhao’s 2022 derivation is given as from producer-consumer dynamics, as his paper states it, where it was given as from network optimisation. In the same list of Section 12, the paper of Banavar and co-authors of 2010 is given its own result, 2/3 when the velocity of flow is constant and at most 3/4, where it was counted among the derivations of the formula, and Bettencourt (2013) the exponent he derives for a city’s land area, $D/(D+H)$, which takes the form only when $H = 1$; the list now counts the formula as derived in its general form or as a special case. The gated simulation of Paper VIII was counted as a positive experiment. The abstract counted it among the empirical studies as a clear positive result, and the plain-English summary beneath it called it positive; Table 1 placed it in a tier of its own, Positive (single experiment), at moderate strength, and Tables 2 and 3 graded it positive; the captions of Tables 1 and 2 and Section 9 counted it as one positive beside one null and one inconclusive result, and the plain-English summary of Table 1 gave it a B; Sections 2, 3, 4.4, 10 and 13 called it the only experiment that produced a clear positive result; the heading of Section 4.4 said that it confirms the Babylon fingerprint, its result paragraph that it confirmed the reward-hacking fingerprint, and Tables 1 and 2 that its drag control was confirmed; Sections 3 and 4.4 said that it succeeded where the other experiments failed, and Sections 3, 4.4 and 13 that the Eden Protocol had produced an effect measurable on the endpoints used at the architectural level. These places now report it as a simulation result, never as an empirical outcome, and between them give what it showed: the Babylon reward-hacking fingerprint, a gain of 4.5 per cent in capability for a loss of 2.4 per cent in safety, and a drag control that matched the static baseline exactly. Section 4.4, which stands under What Is Proven, now says that the simulation is not among what is proven, and quotes the theory registration’s classification of its result; it said that the Eden condition preserved safety, and it now gives the Eden condition’s capability and safety scores against the static baseline’s, as Paper VIII does. Sections 3, 4.4 and 10 gave the design of the simulation, deterministic metrics on a system without pre-existing RLHF training, as the reason for its result; they now give that as the candidate account Section 7.12(c) records, and the abstract, which called it the one experiment in the programme of that design, now calls it the one Paper VIII experiment of that design. The plain-English summary of Section 4.4 gave the source of the cost of safety as a general fact; it now gives it as what the simulation showed. Table 2 graded the simulation of Paper VI as supported, and Tables 2 and 3 said that entangled safety prevents collapse across twenty adversarial seeds; both now report it as a simulation result and give what Paper VI reports: collapse averted in a single-seed run and, across the twenty seeds, a separation on safety retention and none on collapse. Section 7.12(c) refers to the account of why the gated simulation showed the pattern, where it said why it succeeded. The abstract gave the resistance of RLHF-trained models to prompt-level differentiation and the strength of instruct tuning against LoRA as the reasons for the null and the inconclusive result; it now gives each as the candidate account Section 7.12(c) records. It said that every remaining study gave statistically significant findings under blinded evaluation; it now gives what each paper reports: such findings in Papers IV.a to IV.d; in Paper II, a parallel exponent at or close to zero in four of five models, an earlier estimate that did not replicate, and a sequential exponent that comes from the fit of one model and is inconclusive; in Paper V, significant gains scored across models and not under the four-layer blinding protocol; and in Paper VII, a match that is significant under a permutation test, in a structured prediction comparison and not a blind trial. Section 6.2 gave hardware-level embedding a readiness level of TRL 0-1, with no prototype, and a programme of five to ten years; it now gives what version 6.3 of Eden Engineering prints: four mechanisms graded separately, from TRL 4-5 to TRL 1, with timelines from 1-2 years to 10+ years, and a falsification condition recorded as untested and requiring a hardware prototype. Editorial: the abstract called Recursive Dynamics a proposed field, and Section 1.2 and Table 3 called its founding paper the field proposal; the abstract now names Recursive Dynamics as the field the author founded, and Section 1.2 and Table 3 call that paper its founding paper. Section 13 keeps the status the founding paper itself gives the field: proposed, at the Carnot stage. The plain-English summary of Section 7 dates the five corrections of Section 7.12 to version 2.4, and Section 4.3 no longer names the version of Paper VII that carries the permutation test. The reference entries for Papers I and IV.c, Eden Engineering, the Darwin Gödel Machine and Zhao (2022) print the titles, authors and identifier their official records give; the entry Demetrius (2010) named an article that does not exist and now gives the 2008 book chapter that carries its title; the entry He and Chen (2003) names the one record of theirs that could be found; the entry Sandberg and Bostrom (2008) says that no official online copy is available; cited works are linked to their official sources where one could be confirmed, and the programme’s papers to their DOIs; the book and the two sources named in the copyright notice are linked; the page’s title, dateline, citation records and structured record carry the new version and date. No registered law, prediction, kill condition or dependency changes; no result is added; no date of any claim moves. First published 18 March 2026; that date is unchanged. v2.4 - 20 September 2026. Substantive: five corrections are added as Section 7.12, and the correction tally moves from fourteen to nineteen. The displayed solution in Section 6.1 is restricted to the open leverage interval, with the exponential branch at one and the finite-depth branch above it named. Section 7.1 returns the wide interval to the retracted estimate it belongs to and prints the later estimate's own interval, which settles neither the sign, nor the regime, nor the comparison with the bound. The null result is recorded as no difference detected on the endpoints measured rather than as identity, and the root causes standing beside the null and the inconclusive result become candidate accounts with rival accounts left open. Section 4.3 names which null the proportion comparison is taken against and holds to the permutation as primary. The paragraphs that depend on Papers V, VI and VIII point to the corrected passages instead of restating them, and the Paper V phrasing is scoped to the five runs that could be scored, of six run. Three proposed repairs were refused and the refusals are recorded with the corrections. Also substantive: the preregistration estate is stated at seventy, the number the register carried when it was last generated; an earlier entry in this block prints seventy-four as at 1 September 2026, and that entry stays as written because it records what v2.1 set, seventy being the register's figure; the founding paper's conceded objections read thirty-nine, correcting the thirty-eight printed at v2.3; the convergence register's rows read thirty-three; Paper XII shows at protocol stage rather than as a registered protocol, the monograph's prediction ledger as dated rather than registered, and the monograph as speculative; and reviews run inside the programme are no longer called independent, in Section 7.9, in the Paper XI row of Table 3 and in the reference title for Paper VIII. Editorial: Paper VII is cited at v3.11 and the Recursive Dynamics founding paper at v2.8 in both the map and the reference list; the retracted point estimate carries the word retracted in the heading and first sentence of Section 7.8; the two table captions take this version's date; the served comment above Section 3 matches its heading; and an instruction to an editor is removed from the body of Section 7.1. No result, no reported figure and no status has been recomputed, and nothing is submitted anywhere. First published 18 March 2026; that date is unchanged. v2.3: The founding paper’s objections read fifty-one, thirty-nine of them conceded in full or in part, after one objection was withdrawn on 16 September 2026. The figure of thirty-eight printed at v2.3 was wrong and is corrected here. No claim, date, result or status has changed. v2.2: The provenance note at the end has been corrected for accuracy. No claim, date, result or status has changed. Paper IX v2.1 - 2 September 2026: the Paper VIII tally now reads one null, one inconclusive and one positive across three experiments, where the text had claimed two nulls across four; Paper V leaves the proven row of Table 1 for a supported one, in step with Section 4.2, and its five analysable runs and three loops now carry the names Paper V gives them, the superseded text having listed GPT among the five and having described loops Paper V does not test; Paper VII’s headline is the permutation test, with the binomial standing beside it as a sensitivity check, and the negative controls are attributed to the v1 run and its record; the account of scoring is put right, a purpose-built Claude Sonnet scorer adapter having scored the Claude Opus run; the self-reference exponent takes the subscript βL that the notation spine sets; the measured exponent appears with its interval, and the parallel exponent as four of five models; the preregistration estate stands at seventy-four (as at 1 September 2026); the window in which the programme was produced runs to the present; Table 1 carries this version’s date; Eden Engineering shows as withdrawn in Table 3 and in the footer; and the reference titles for Papers IV.a, IV.b and VII are corrected. v2.0 - 1 September 2026: a structural refresh drawing in Papers X to XIII, HRIH, Paper C and the Recursive Dynamics founding paper.
Epistemic status. What this programme names Laws are conjectures. Laws I to III are under registered adversarial test. Laws IV and V were added on 24 September 2026; the predictions that carry them are registered, the laws themselves are not yet registered, and neither has been tested. Every quantity in this paper is operationally defined, and established-law standing is claimed nowhere. The registered programme exists to earn that standing, or lose it, by measurement, replication and survived refutation.
© 2026 Michael Darius Eastwood. Full human authorship and moral rights are asserted under the Copyright, Designs and Patents Act 1988 and consistently with United States Copyright Office guidance on works containing AI-generated material; any novel technical contribution described in this work was conceived by the human author. Full statement: michaeldariuseastwood.com/authorship.
Standing covenant. Prove this paper wrong, and I will publish the refutation myself. Falsification conditions are stated in this paper; the standing challenge: github.com/MichaelDariusEastwood/arc-scaling-challenge.
Michael Darius Eastwood conceived and directs this research programme and is the author of this work. Across the programme, he has used more than six AI systems in parallel, under his own instructions, to stress-test his arguments, identify possible errors, and assist in preparing draft text from his own outlines. He determines what is adopted, revised or rejected and takes responsibility for the published content. These systems are tools, not authors.